🎧 MiDashengLM-Spatial
Unifying General Audio Understanding and Spatial Awareness
Overview
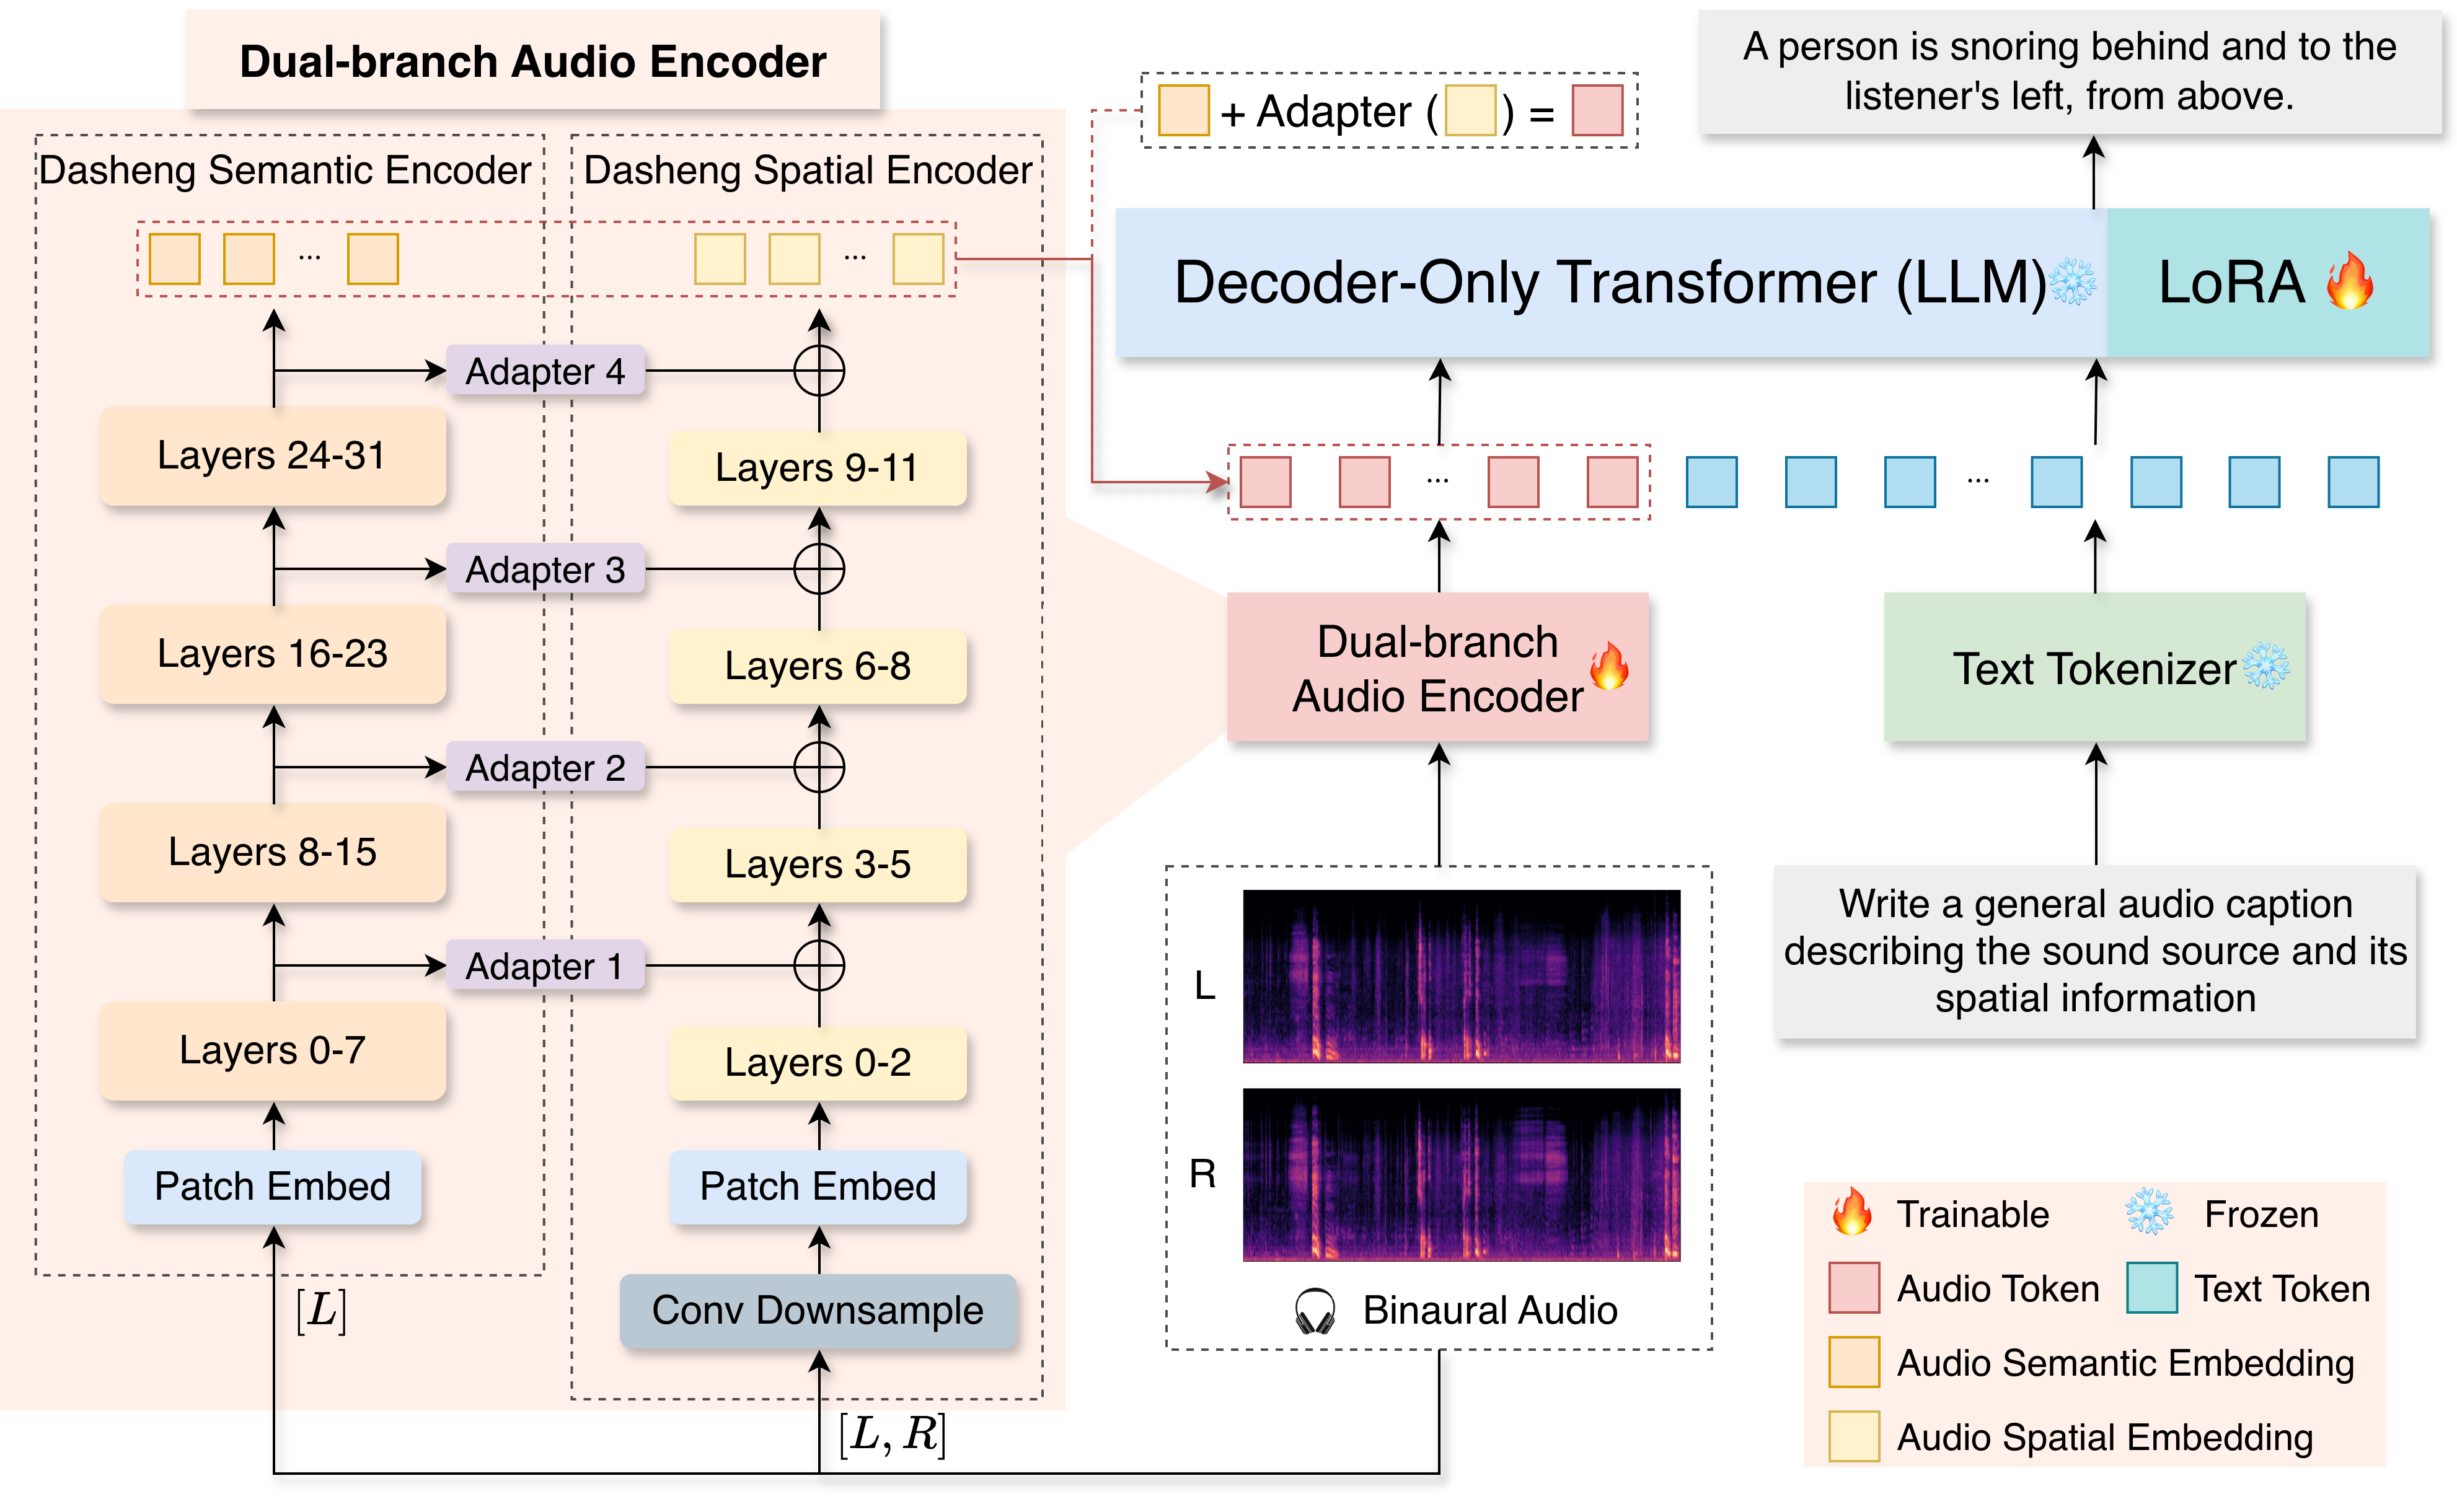
MiDashengLM-Spatial, to our knowledge, is the first open-source end-to-end unified audio-language model that supports both general audio understanding and spatial awareness within a single architecture. It extends MiDashengLM with Spatial-Dasheng through a hierarchical semantic-to-spatial conditioning (HSSC) module to separately capture and effectively integrate semantic and spatial audio information. This design enables binaural perception and spatial audio understanding capabilities while preserving general audio understanding capabilities of the base model.
Highlights
- Unified general audio understanding and spatial awareness — the unified audio-language model that supports both general audio understanding and spatial awareness within a single architecture
- Spatial-Dasheng — a spatial audio encoder that performs frame-wise detection and localization of overlapping sound events
- Hierarchical Semantic-to-Spatial Conditioning (HSSC) — a conditioning mechanism that hierarchically conveys intermediate semantic representations from the semantic branch to corresponding layers of the spatial branch, allowing spatial modeling to leverage semantic context while preserving the functional separation of the two branches
- Scalable spatial-scene synthesis — a data pipeline that constructs 1M spatial acoustic scenes (~13,000 hours) involving environmental sounds, speech, and music, together with rich scene-level spatial descriptions and 6M fact-verified QA pairs
- Robust spatial awareness without compromising generality — extensive experiments demonstrate that Spatial-Dasheng delivers robust spatial perception and sim-to-real generalization, while MiDashengLM-Spatial acquires spatial awareness without sacrificing general audio understanding
Architecture
Binaural Audio Demonstrations
🎧 Best experienced with headphones.
Citation
@article{hu2026midashenglmspatial,
    title={MiDashengLM-Spatial: Unifying General Audio Understanding and Spatial Awareness},
    author={Jinbo Hu and Hang Su and Lichun Fan and Heinrich Dinkel and Gang Li and Zhanchen Dai and Yiru Zhang and Chang Liu and Peng Wang and Junnan Wu and Jian Luan and Cong Zou and Heng Qu},
    year={2026},
    journal={arXiv preprint arxiv:2610.11156},
}
Licensed under the Apache License 2.0.